01
Perception
Vision Models
Detect, track and structure the visual signals that matter across people, objects, movement and events.
- Detection
- Tracking
- Evaluation
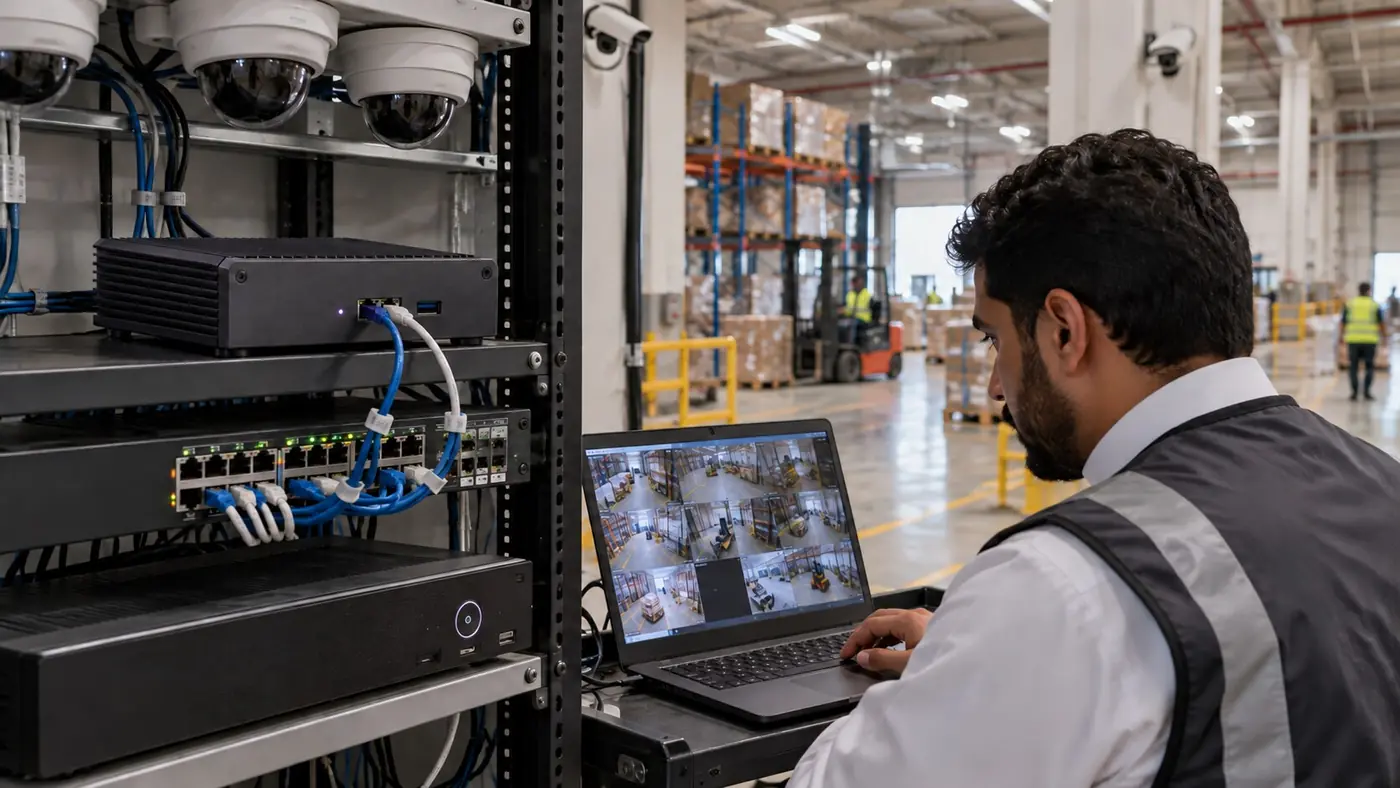
Deqa combines visual models, VLM reasoning, an AI Agent Harness, customer SOPs and edge compute so video becomes governed evidence and action.
Four connected layers make the AI Agent useful, controllable and ready for real customer operations.
Perception
Detect, track and structure the visual signals that matter across people, objects, movement and events.
Multimodal context
Understands scenes over time by combining video, language, site context and the customer’s operating question.
Governed orchestration
Connects the VLM to tools, memory, policies and enterprise APIs so reasoning becomes safe, observable action.
Executable operations
Turns customer SOPs into triggers, permissions, escalation paths and the evidence required to close every loop.
Deqa Box is the secure edge runtime for visual models, VLM reasoning and the local side of the Agent Harness. It keeps critical workflows fast and resilient while respecting privacy and bandwidth constraints.
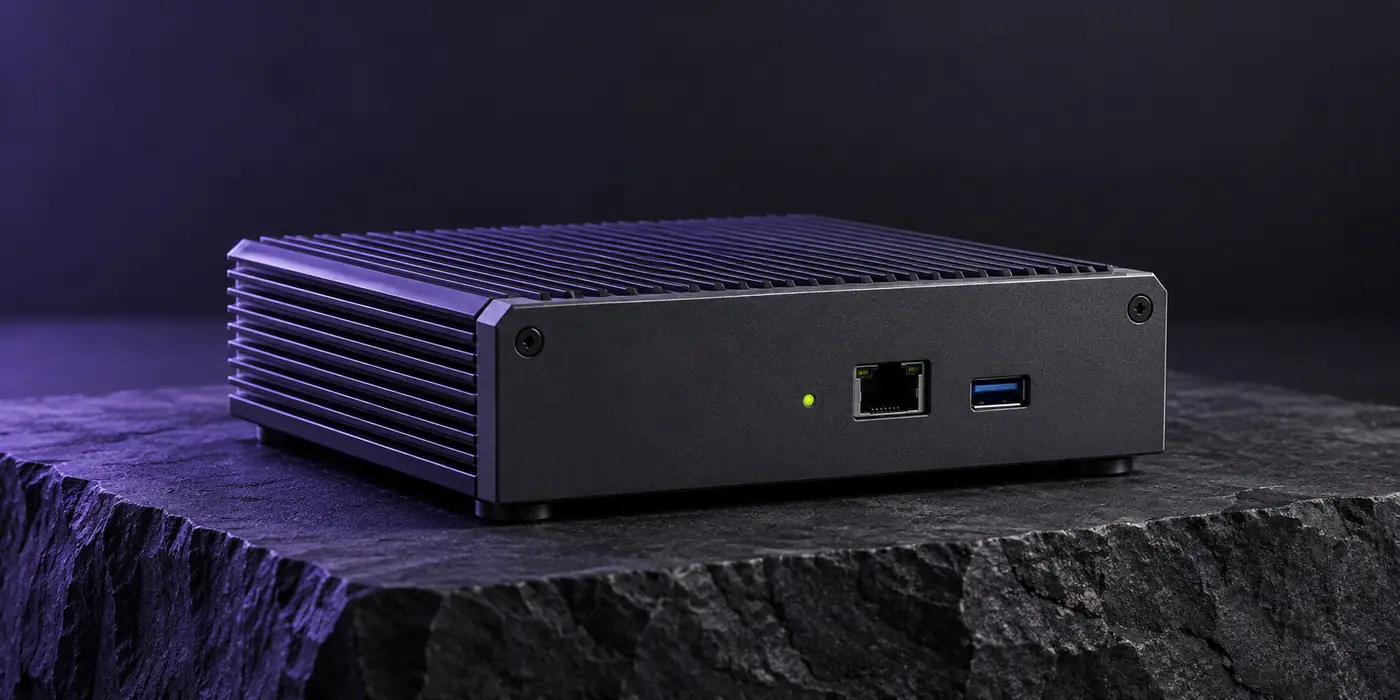
A transparent operating stack designed for bandwidth, latency, privacy, permissions and enterprise integration constraints.
CCTV · Drones · Dashcams · Mobile
Edge inference · Secure buffer · Local runtime
Context · Tools · Memory · Guardrails
Decisions · Escalation · Evidence · APIs
Near-camera inference for low latency and limited bandwidth.
Private operation inside the customer network.
Central management for distributed multi-site operations.
Real-time edge action with governed cloud aggregation.
Journeys · queues · dwell · conversion
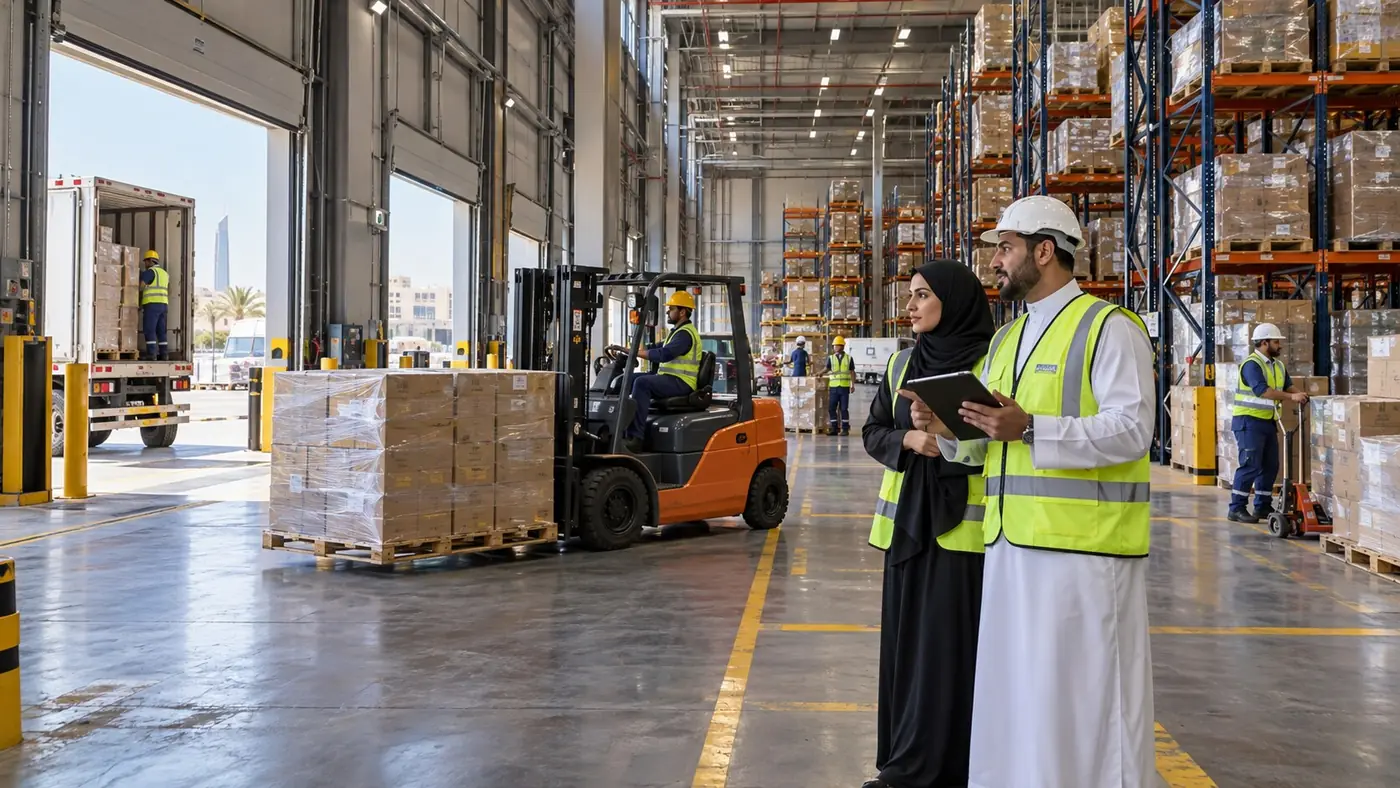
Flow · loading · dwell · evidence
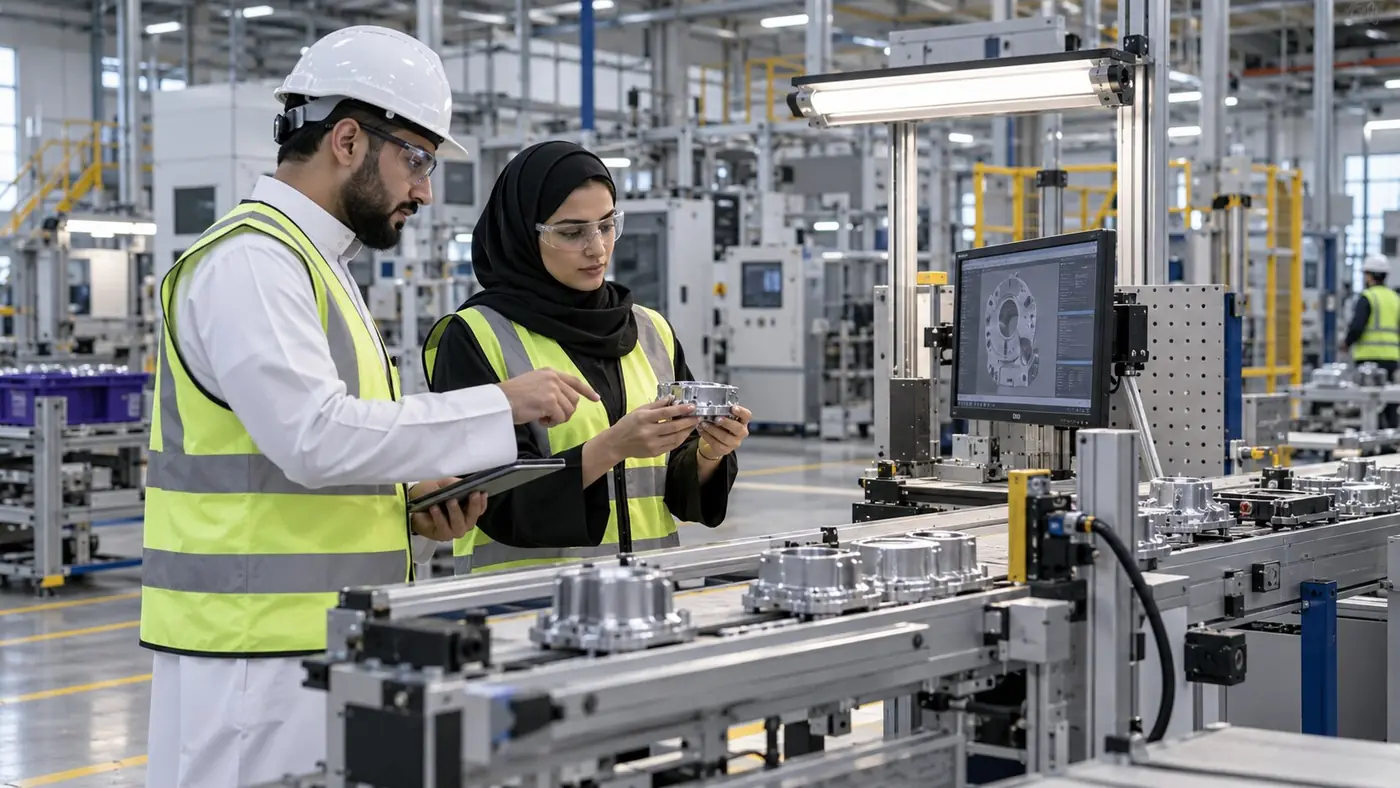
Safety · quality · assets · SOPs
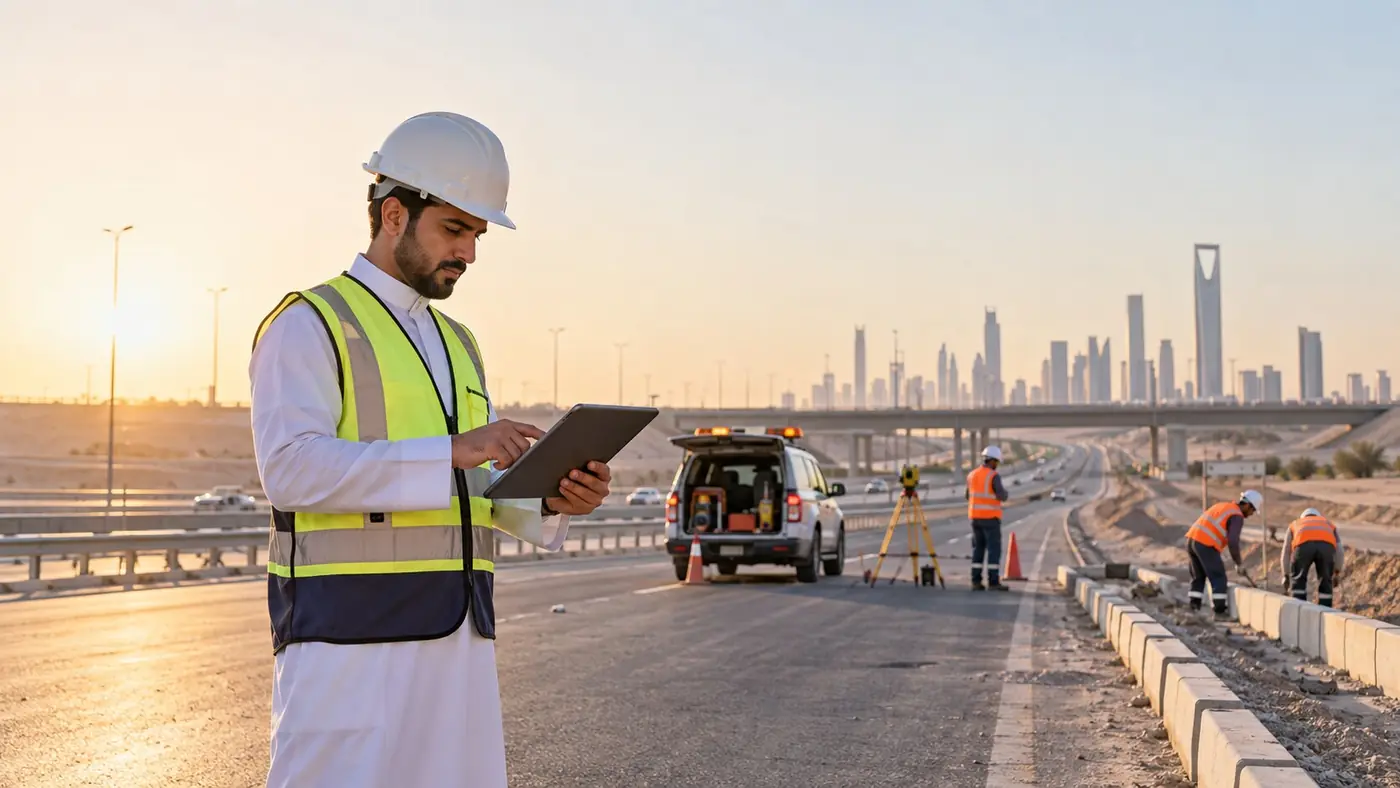
Attendance · tasks · roads · sites